Pillar guide
Zero-downtime deployment for Go
What zero-downtime deployment means for a Go service, and how Phelix delivers it: a reverse proxy, blue-green and rolling releases, canary rollouts, health gating, and rollback.
Released Phelix hosts: Linux and macOS. Builds Go and Rust with your host toolchain.
simulated
a candidate starts beside the serving version · traffic never waits
What zero-downtime deployment means
Releasing a new version without a window where requests fail.
A naive deploy stops the running process and starts the new one. For the seconds in between, requests have nowhere to go. Zero-downtime deployment removes that gap: the new version comes up and proves itself before any traffic moves to it, and the old version keeps serving until the switch is complete. Phelix treats this as the default path rather than an add-on. It picks from classic, blue-green, rolling, and canary strategies, described in deployment strategies, and only classic accepts a brief interruption.
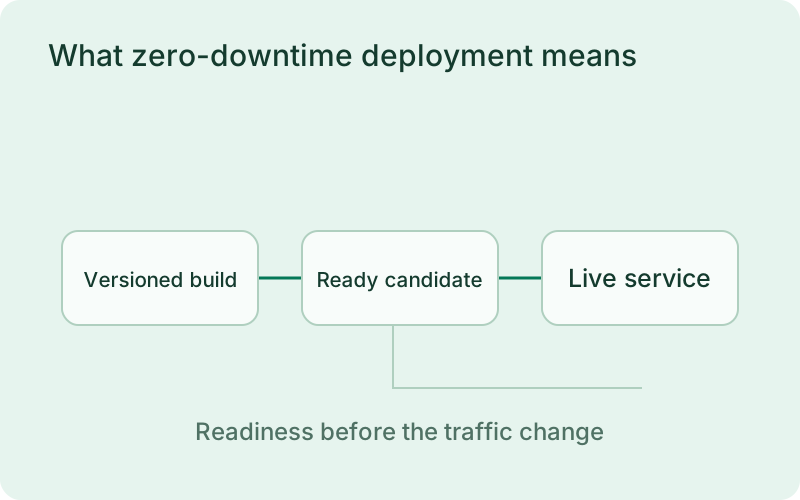
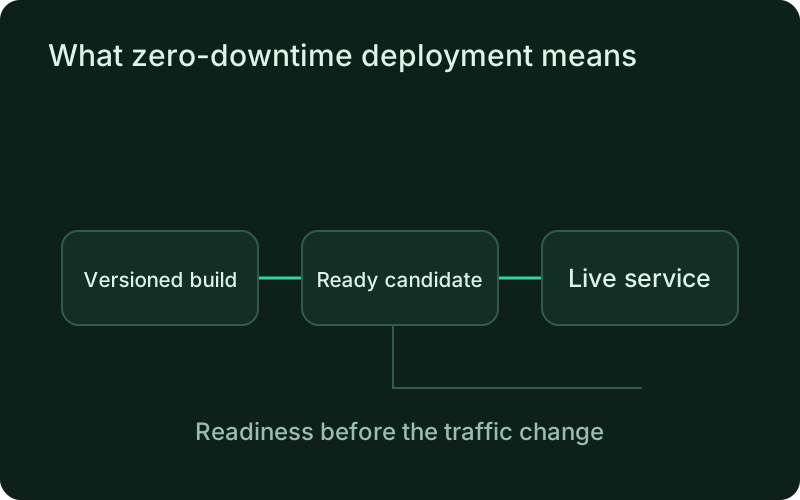
This matters most for services where a short interruption affects customers or interrupts dependent work. Preserve availability by preparing the candidate before it takes over, while keeping enough capacity for the overlap. Plan compatible data changes and graceful shutdown alongside the traffic strategy, because maintaining a listener alone cannot protect every customer interaction during a release.
A reverse proxy in front of your app
Traffic reaches a host-local proxy, which routes it to the healthy instance.
The proxy is what makes an atomic, safe switch possible. Clients connect to the proxy; the proxy forwards to whichever instance is currently healthy. During a deploy, Phelix changes proxy membership rather than restarting your listener, so the public endpoint never goes down. The proxy model and its persistence are covered in zero-downtime deploys.
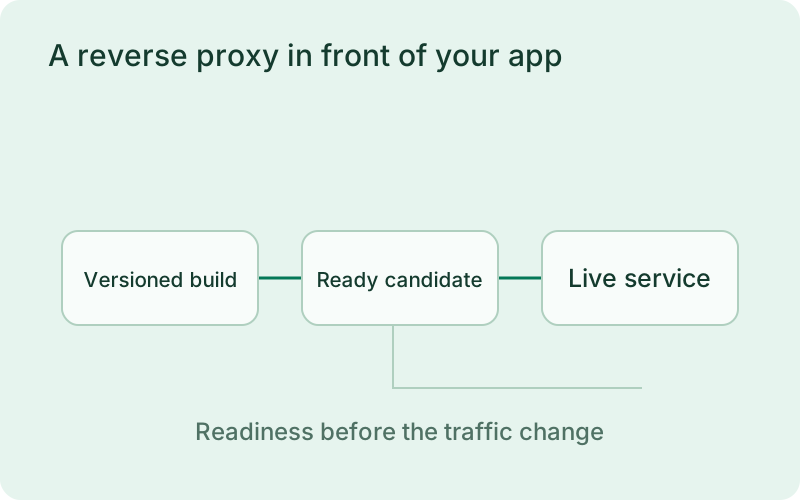
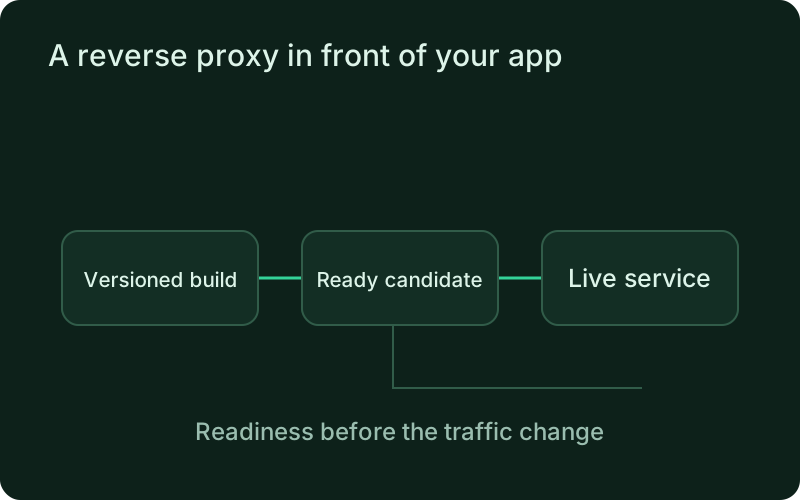
The public address can stay stable while the healthy instance behind it changes. That separates the customer connection point from the application process being replaced. Keep the proxy configuration and the host network part of your operating review, since a host-local switch does not provide another machine to serve requests when the entire server becomes unavailable.
Blue-green and rolling releases
Start the new version beside the old one, health-check it, then switch.
Blue-green brings up a full candidate, health-checks it, and cuts the proxy over in one move while the old version drains. Rolling replaces replicas one at a time, so capacity stays up throughout the release. Both are detailed in zero-downtime deploys.
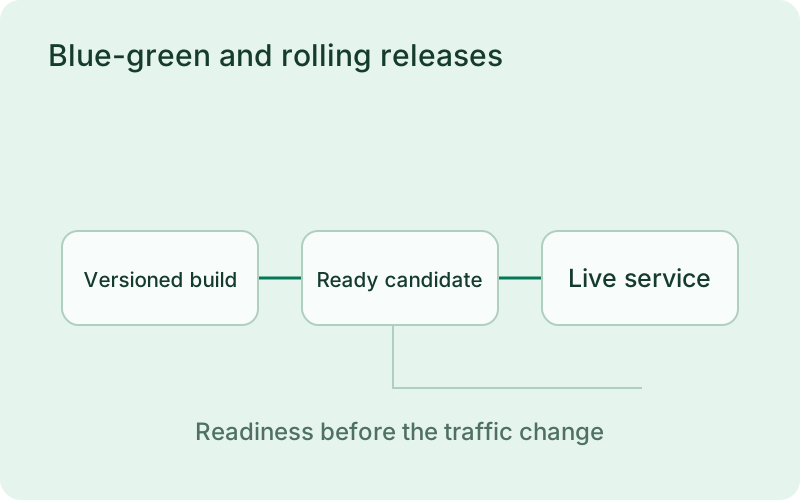
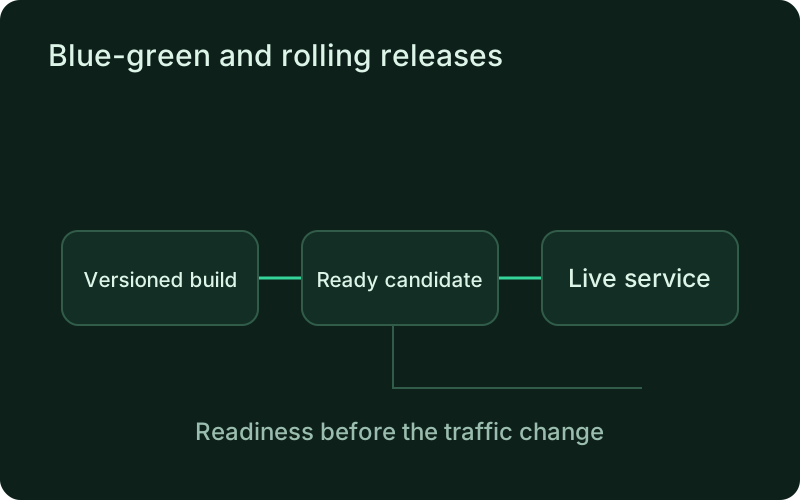
Choose the strategy around the service and the host capacity. Blue-green gives one switch between slots, while rolling introduces a release through a replica set. During either overlap, old and new versions need to understand shared data and request formats. Review those contracts before release rather than expecting the replacement order to make incompatible behavior safe.
phelix deploy api --blue-greenCanary and progressive rollouts
Send a share of traffic to the new version, verify it, then promote.
A canary routes a slice of live traffic to the new version and compares it against the stable baseline using verification thresholds. A progressive rollout steps the share up as it keeps passing, and backs out automatically if it does not. See canary and progressive rollouts.
A smaller initial traffic share can make a behavioral regression easier to notice, but only when useful measurements exist. Review the baseline, observation period, and verification thresholds for the service. Quiet traffic or missing signals can limit the evidence, so do not confuse a gradual rollout with proof that every customer-facing operation has been exercised.
phelix deploy api --canary 10Health gating decides the cutover
A version takes traffic only after it passes its checks.
Every proxy-based strategy is gated on health. Phelix supports explicit HTTP readiness with automatic HTTP, TCP, and PID fallbacks, so a candidate that never becomes ready never receives requests, and an instance that goes unhealthy later can trigger bounded recovery. The tiers and modes are in health checks. Health checks reduce risk; they do not prove that every behavior of your application is correct. A candidate that passes its checks can still be wrong, which is exactly why rollback matters.
Test readiness during startup and when an essential dependency fails. An explicit application response provides stronger evidence than a running process or an accepting port. Keep those limits visible during release review, then observe errors and response times after the switch to catch problems that the startup gate could not show.
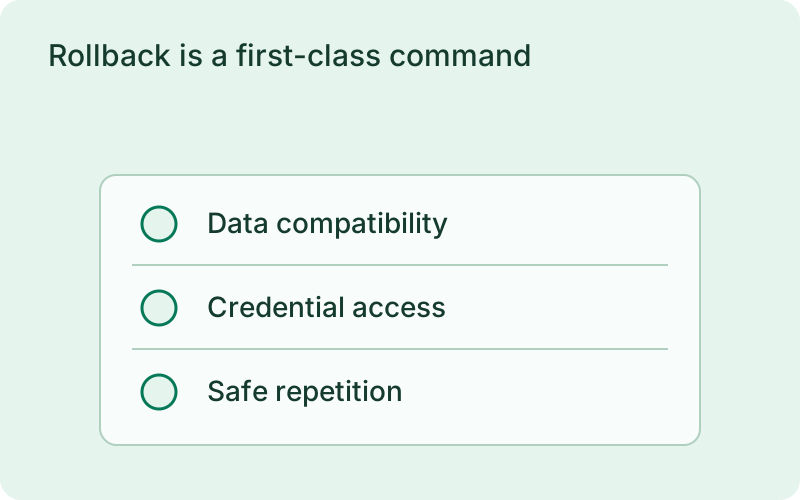
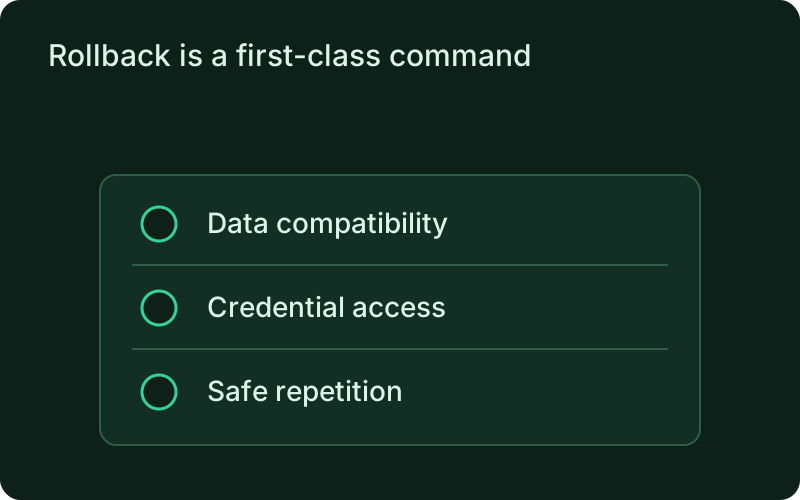
Rollback is a first-class command
Return to a retained version through the same topology, binary and environment together.
When a release is wrong, roll back to a retained valid version. Phelix reuses the application's current deployment topology, runs the applicable health checks, and records the outcome. Proxy-based rollback can health-gate the switch; classic rollback can have brief downtime. The mechanics and retention rules are in versions and rollback. The binary and its encrypted environment snapshot roll back together, so a restored version runs with the configuration it was built against. That model is described in environment and security.
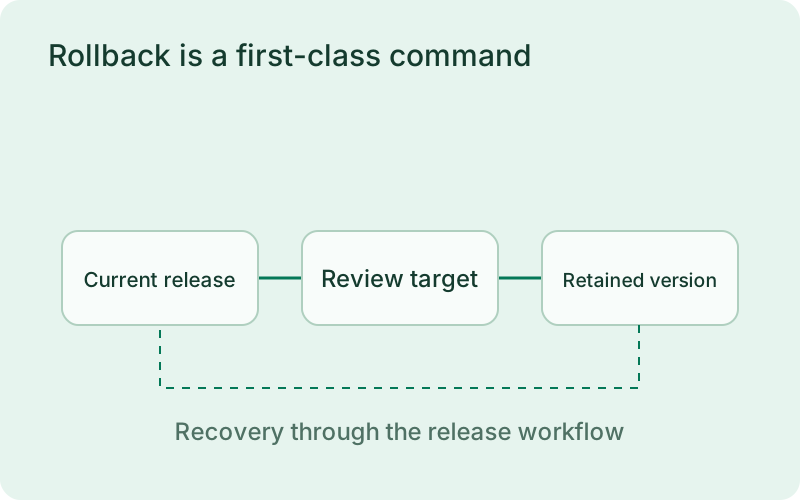
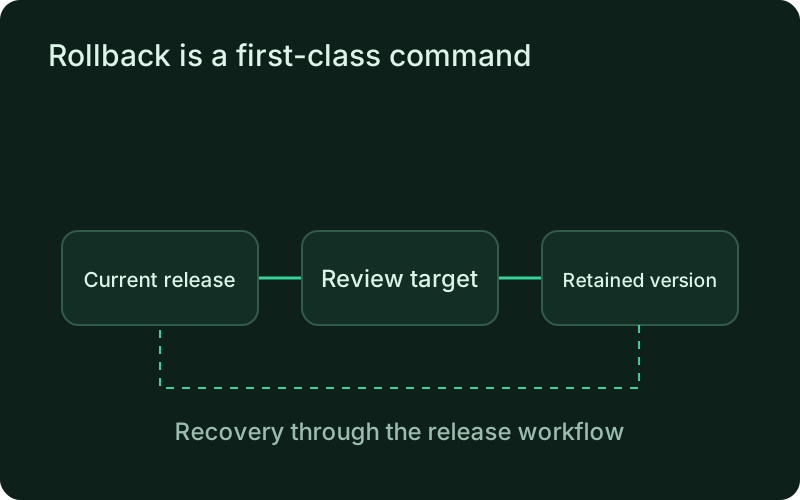
Choose a recovery target that still works against current databases, message formats, and external integrations. Preview the intended restoration, then confirm the customer operation recovers after traffic moves. Ordinary environment snapshots accompany the restored binary, while dedicated secrets retain their current bindings and external side effects are not reversed by restoring an application version.
Zero-downtime FAQ
Short answers, with the full detail in the docs.
Does Phelix deploy applications without downtime?
Blue-green and rolling deployments start and health-check a candidate before changing HTTP proxy membership. Classic deployment is stop → start and can have brief downtime. Health checks reduce risk but do not prove that every application behavior is correct.
What happens when an application becomes unhealthy?
Repeated endpoint-health failures can trigger bounded restart attempts with an attempt cap. During deployment, an unhealthy candidate stays off traffic. If restoration fails, Phelix records a degraded state that requires manual intervention.
Can I roll back an application?
Yes, to a retained valid native version. Phelix reuses the application's current deployment topology, runs applicable health checks, and records the outcome. Proxy-based rollback can health-gate traffic switching; classic rollback can have downtime.
Agent-driven, still zero-downtime
New in v1.1.0: a coding agent can run the cutover without weakening a single guarantee.
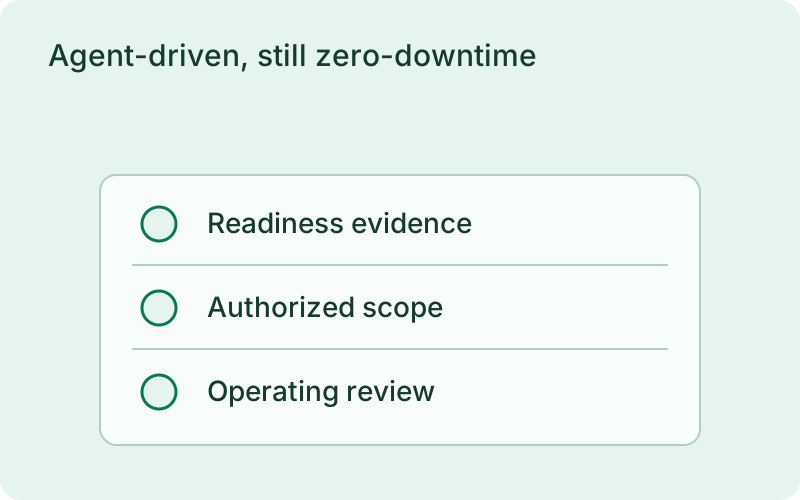
A built-in MCP adapter lets Claude Code or Codex propose a zero-downtime Go deploy as an immutable plan and apply it through the exact health-gated pipeline described above. The execution-authorization boundary keeps every apply plan-bound and human-approved, so the blue-green or canary cutover an agent triggers is the same one you would run by hand.
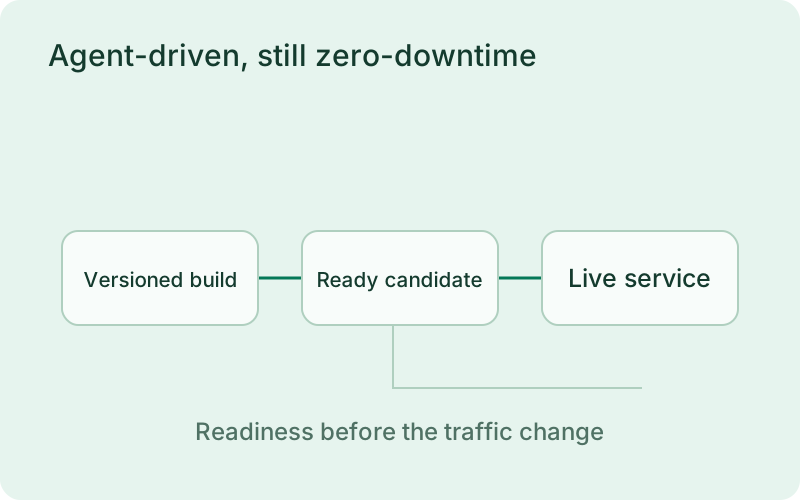
An assistant can request the same release without changing who decides whether production should change. Review and approve the exact plan, then watch the normal readiness and traffic transition results. If the proposal is wrong, replace it before execution. After an approved rollout, check service behavior just as carefully as after a release started by a person.
One binary between git push and production.
Install the CLI, verify the host, and follow the quick start to build your first application.